Why this works
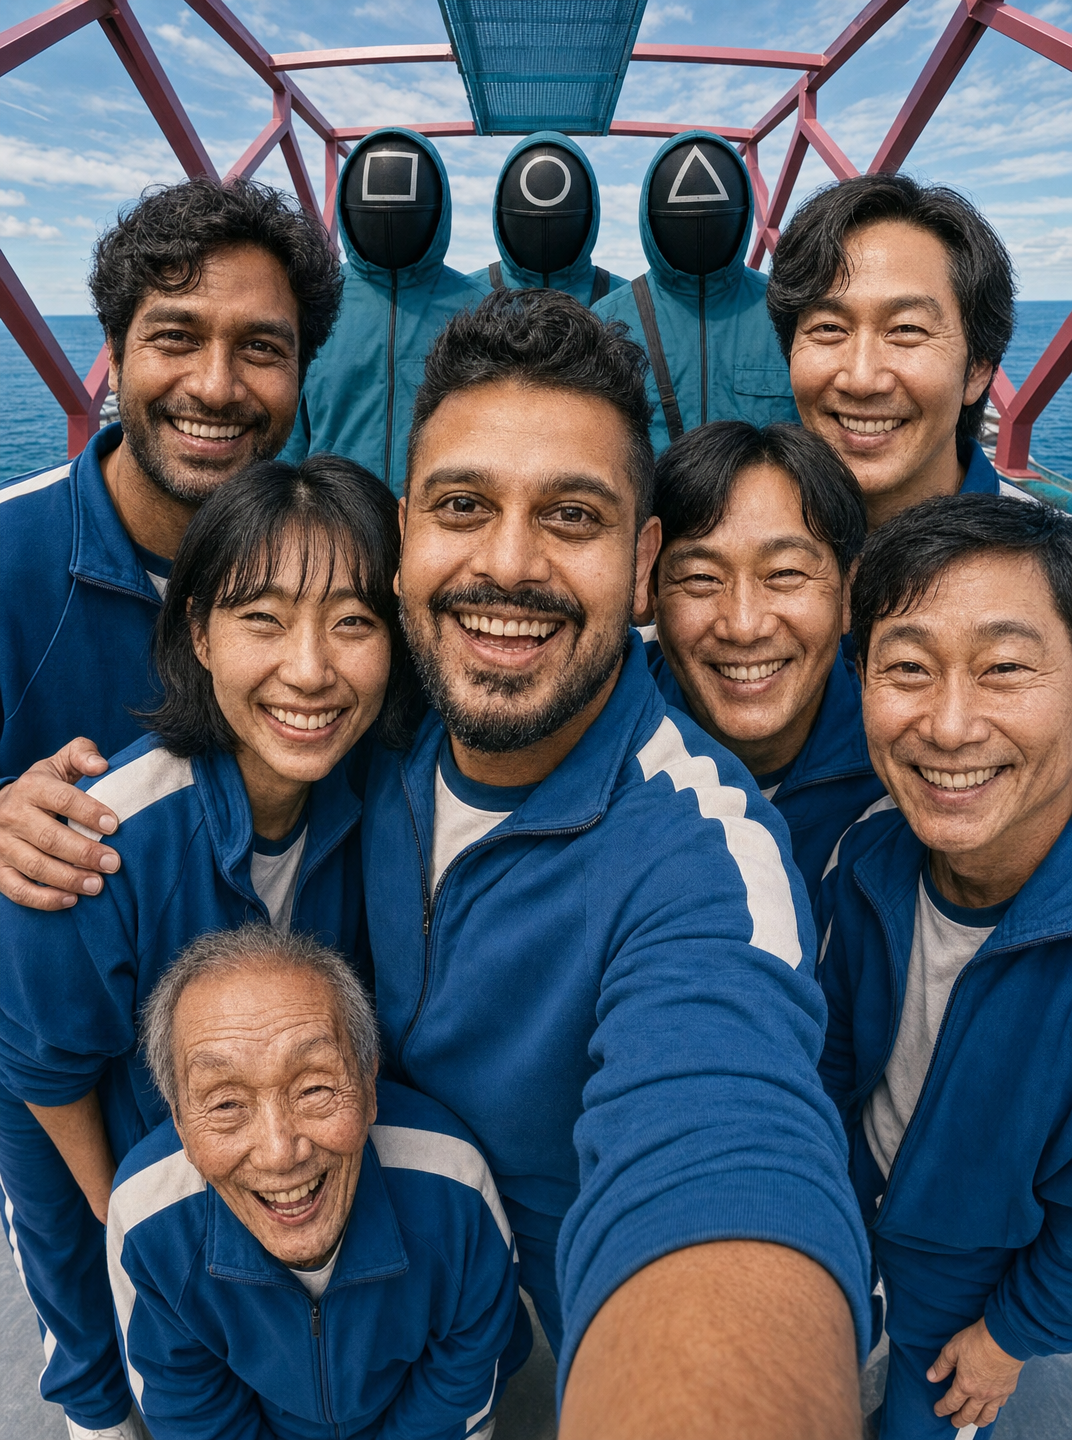
“Vertical fisheye selfie framing” bends the glass bridge and steel frame toward the edges, making the candid group feel close, energetic, and slightly exaggerated. The contrast between “eight smiling adults in coordinated blue tracksuits” and “three masked guards in teal hooded uniforms” supplies the playful-versus-dramatic mood, while “bright sky with thin clouds,” “geometric steel frame,” and “glass floor” organize the image into sky-blue, gray, black, and white structural bands. “Crisp focus,” “high-detail faces,” and “natural reflections on the glass floor” keep both the expressive foreground faces and the arena setting legible despite the wide-angle composition.
FAQ
→How do I make the masked guards the central, more intimidating element?
Replace “eight smiling adults in coordinated blue tracksuits” with “eight tense adults clustered at the edges of the frame,” and change “three masked guards in teal hooded uniforms pose confidently behind them” to “three towering masked guards in teal hooded uniforms standing closest to the camera, dominating the center.” Replace “smiling adults” with “worried, rigid expressions” and “playful, energetic, dramatic” with “ominous, controlled, high-tension.”
→How do I shift this from a bright playful scene to a darker thriller?
Replace “bright sky with thin clouds visible beyond” with “storm-dark sky with heavy clouds and distant lightning,” and change “vivid but slightly cooler color palette” to “desaturated blue-gray palette with stark red warning lights.” Replace “eight smiling adults” with “eight anxious adults,” and change “hyper-realistic cinematic lighting” to “hard directional lighting with deep shadows and narrow beams across the glass floor.”
→How do I build a series of variations without losing the visual identity?
Keep “ultra-realistic 8k,” “vertical fisheye cinematic group selfie,” “coordinated blue tracksuits,” “three masked guards in teal hooded uniforms,” and “glass bridge arena” unchanged. For each variation, replace only “bright sky with thin clouds” with settings such as “neon-lit rooftop at night,” “fog-filled industrial corridor,” or “sunset suspension bridge,” then swap “energetic composition” for “low-angle formation,” “overhead symmetrical composition,” or “motion-blurred running selfie” to create distinct episodes.
Learn the technique behind this
- Why can't AI spell, and how do I get readable text in an image? — Older diffusion models had no character-level representation of text, so they produced letterform-shaped texture instead of words.
- How should a prompt be structured, and does word order matter? — A prompt that behaves predictably names one subject first, then what it is doing, then where, then the light, then the lens or medium, then the style.
- Why does the model ignore parts of my prompt? — Ignored instructions are almost always conflicts, counts, or spatial relationships — three things current models handle badly — rather than the model failing to read you.
Related prompts
Woman's Selfie with Crimson-Powered Anime Guardian
Golden-hour selfie at outdoor cafe
Couple selfie in warm golden light
Young woman with auburn hair holding peach bouquet